

Rob Gibbon
28 posts
The purpose of this guide is to highlight the key differences between Apache Spark 3 and Spark 4, and provide advice on how to plan a migration. Let’s get...
What is llm-d? llm-d is an open source solution for managing high-scale, high-performance Large Language Model (LLM) deployments. LLMs are at the heart of...
Many of us are familiar with the retrieval augmented generative AI (RAG) pattern for building agentic AI applications – like digital concierges, frontline...
Apache Spark is a popular framework for developing distributed, parallel data processing applications. Our solution for Apache Spark on Kubernetes has made...
Move over Hadoop, it’s time for Spark on Kubernetes Apache Spark, a framework for parallel distributed data processing, has become a popular choice for...
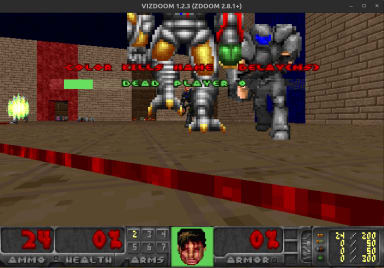
It’s all about AI these days, so I decided to try and answer the important question: can you make a Spark cluster run AI agents that play a game of Doom, in a...
Download the Spark reference architecture guide In this post we’ll explore deploying a fully operational, on-premise data hub using Canonical’s data centre...
In the early 2010s, Apache Hadoop captured the imagination of the tech community. A free and powerful open source platform, it gave users a way to process...
Charmed Kafka is a complete solution to manage the full lifecycle of Apache Kafka. The Canonical Data Fabric team is pleased to announce the first beta...
We’re super excited to announce that we have shipped the first release of our solution for big data – Charmed Spark. Charmed Spark packages a supported...

I’ve read and watched more than a few articles about ChatGPT in the last couple of months. It seems the large language model AI hype machine just can’t stop. ...
The Canonical Data Fabric team is pleased to announce the first beta release of Charmed Spark, our solution for Apache Spark. Apache Spark is a free, open...
We’ve all read the headlines about spectacular data breaches and other security incidents, and the impact that they have had on the victim organisations. And...
Designing a production service environment around Apache Kafka that delivers low latency and zero-data loss at scale is non-trivial. Indeed, it’s the holy...
Software operators are steadily revolutionising how we deploy and run complex distributed systems. They offer the promise of low-intervention, self-driving...
Canonical Data Platform: that was 2021 It’s that time of the year again: many folks are panic buying cans of windscreen de-icer spray and thermal underwear,...